An AI that formalized one of the most famous proofs in mathematics in 30 hours. An AI that designed three working electronic gadgets from a one paragraph prompt. An AI that coordinated more than 1,000 helper agents for eight straight days and built a working operating system from an empty folder.
That’s not a sci fi pitch. It’s what Anthropic says its newest models, Claude Fable 5.2 and Claude Mythos 5.2, did during testing. I’ve followed a lot of model launches this year, and this one stood out to me for a simple reason: the models got smarter, faster and cheaper all at once, which almost never happens.
Claude Fable 5.2 and Mythos 5.2: What Anthropic Launched
On November 9, 2026, Anthropic released Claude Fable 5.2 and Claude Mythos 5.2, its most capable models for the hardest technical work. Both show clear gains in coding, reasoning and vision, and they generate outputs up to 30% faster than the 5.1 versions.
The price also dropped. Both models now cost $8 per million input tokens and $40 per million output tokens, about a 20% cut. A new optional fast mode speeds up output by up to 2.5 times for $16 per million input tokens and $80 per million output tokens.
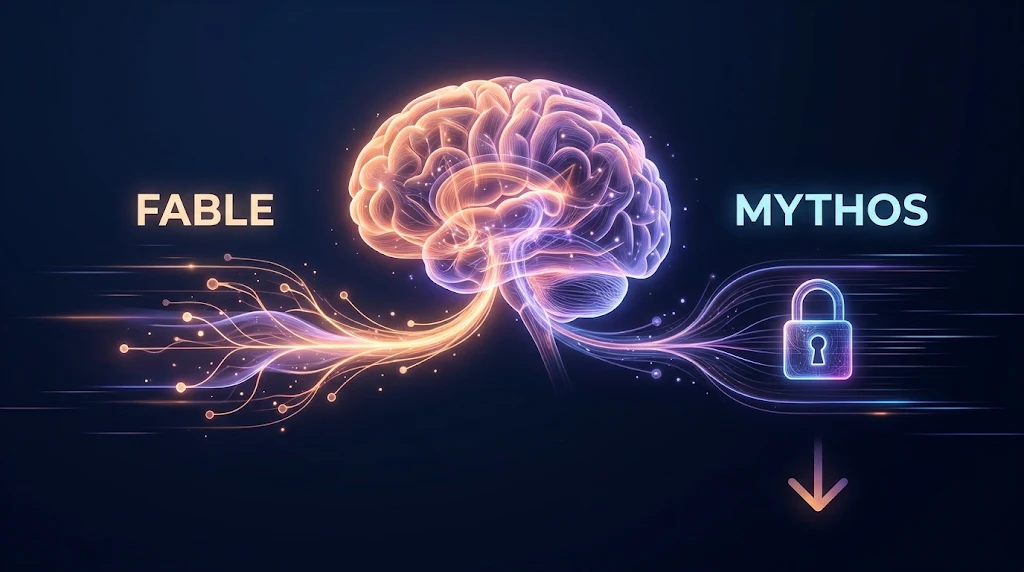
Here’s the twist many people miss: Fable and Mythos are the same underlying model. The difference is the safety guardrails. Fable 5.2 has strong cybersecurity and biology safeguards, so it’s available to everyone. Mythos 5.2 has more relaxed guardrails and is offered only to approved organizations doing beneficial work in cybersecurity or biomedical research.
Key Facts at a Glance
- Released: November 9, 2026
- Models: Claude Fable 5.2 (public) and Claude Mythos 5.2 (approved organizations only)
- Speed: Outputs up to 30% faster than Fable 5.1 and Mythos 5.1
- Standard price: $8 per million input tokens, $40 per million output tokens
- Fast mode: Up to 2.5 times faster output, $16 input and $80 output per million tokens
- Availability: Claude apps, the Claude Platform, Amazon Web Services, Google Cloud and Microsoft Azure
- Developer model name: claude-fable-5-2
- Safety testing: Reviewed by outside evaluators including the UK AI Security Institute and METR
Fable 5.2 vs Mythos 5.2: The Real Difference
Think of it as one engine with two different sets of brakes.
| Claude Fable 5.2 | Claude Mythos 5.2 | |
|---|---|---|
| Underlying model | Same | Same |
| Who can use it | Everyone | Approved organizations through verification programs |
| Cybersecurity tasks | Mostly blocked by safeguards | Fully supported |
| Biology and biomedical tasks | Restricted by safeguards | Supported for approved researchers |
| Best for | Coding, finance, science, research, business work | Security research, vulnerability hunting, protein and gene therapy research |
| Price | $8 / $40 per million tokens | $8 / $40 per million tokens |
Access to Mythos goes through Anthropic’s Cyber Verification Program and Life Sciences Verification Program. Enterprise customers who aren’t in those programs can still tap Mythos 5.2 indirectly through Claude Security, a tool that scans codebases for vulnerabilities.
Anthropic also says Fable 5.2’s safeguards are just as strong as before but produce fewer unnecessary blocks, which should mean fewer frustrating refusals on harmless requests.
How It Works: Effort Levels, Fast Mode and Agent Teams
To really understand these models, you need to know three technical ideas.
Effort Levels
You can choose how hard the model thinks before answering: Low, Medium, High, Xhigh or Max. More effort means better answers on hard problems, but more tokens and higher cost. Medium is the default in the Claude apps and Claude Code.
This is where Fable 5.2 gets interesting financially. On the FrontierCode 2.0 coding test, Fable 5.2 at High effort scored about the same as Opus 5.5 at its maximum setting, 45.3% versus 45.5%, for roughly half the cost per task. On Humanity’s Last Exam, a brutal test of expert knowledge, Fable 5.2 at Low effort matched Opus 5.5’s top score for less than one tenth of the cost.
Fast Mode
Fast mode trades money for speed. It doubles the price but speeds up token generation by up to 2.5 times, useful when a developer or analyst needs answers right away.
Advisor and Orchestrator Roles
Fable 5.2 can work as a team leader for other AI models. As an Advisor, smaller models like Haiku, Sonnet or Opus consult Fable when they hit a hard problem. As an Orchestrator, Fable breaks a big job into pieces and hands simpler tasks to faster, cheaper models. Datadog’s Matt Lee compared it to “an incident commander that can send out faster models to get quick signals and coordinate.”
Benchmark Results: How Fable 5.2 Compares
Anthropic tested Fable 5.2 against its own models and rivals like OpenAI’s GPT-6 Astra and Google’s Gemini 4 Carbon. A few results stand out:
| Test | What it measures | Fable 5.2 | Opus 5.5 | GPT-6 Astra |
|---|---|---|---|---|
| FrontierCode 2.0 | Code that real project maintainers would accept | 49.1% | 45.5% | 42.8% |
| FrontierSWE v2 | Software engineering tasks | 69.9% | 62.3% | 65.5% |
| Humanity’s Last Exam (with tools) | Expert level reasoning | 74.2% | 67.7% | 57.2% |
| Remote Labor Index | Real remote work tasks | 41.3% | 21.3% | 20.8% |
| RoboDojo Sim | Controlling a two arm robot | 64.9% | 39.4% | 29.8% |
| OSWorld 2.1 | Using a computer like a person | 89.3% | 87.2% | 79.5% |
It isn’t a clean sweep. On AutomationBench, which tests business workflows, Gemini 4 Carbon scored 53.9%, ahead of Fable 5.2’s 51.4%. But overall, Fable 5.2 leads in almost every category Anthropic tested.
Which Jobs Use Which Features
This is the part I find most useful, because it shows how these models fit into real work.
Software Engineers and Developers
Main features: agentic coding, Orchestrator mode, High or Xhigh effort.
Anthropic says over 90% of changes merged into its own codebase are now written by Claude with human guidance. A team of agents running an early Fable 5.2 version moved a critical service from Python to Rust, and it now starts about 26 times faster. Vercel engineers said projects that dragged on for weeks with other models were finished and approved in a few days.
How it works: You describe the goal, even loosely. Fable plans the work, splits it into tasks, sends helper agents to write and test code, then reviews the results before handing them back.
Security Teams
Main features: Mythos 5.2, Claude Security scanning.
Mythos 5.2 found 10.2% more known vulnerabilities than Opus 5.5 on Anthropic’s CVE Rediscovery test. Mozilla said it roughly doubled the bug discovery numbers of Mythos 5.1 while hardening Firefox. At Uber, Fable 5.2 ran a 10 to 12 hour security audit, sending out about 170 reviewer agents and returning a full report with fixes.
How it works: The model reads a codebase, flags possible weaknesses, reproduces them to confirm they’re real, then writes a fix. Claude Security can now watch code continuously and track whether issues get fixed.
Finance, Trading and Investment Research
Main features: research and analysis, multi agent coordination.
Jump Trading reported 10% lower error than the next best model on an internal research test. Oracle found Fable 5.2 wrote correct database queries where two rival models produced totals five to eight times too high. Fundamental Research Labs said it caught regional numbers that didn’t add up in a company’s annual 10-K filing.
How it works: Fable reads financial documents and data, builds models or queries, and checks its own math against reported totals before answering.
Scientists and Researchers
Main features: agentic scientific research, Mythos 5.2 for biology.
Fable 5.2 solved two open problems about black holes in theoretical physics. Mythos 5.2 found a new way to predict the full structure of virus shells used to deliver gene therapies, accurately modeling 28 of the 34 it attempted. Discovered Materials said it made a key materials science calculation about 36 times faster, cutting 3.3 hours of work to under four minutes.
Mathematicians
Main feature: large agent teams.
A team of 1,000 Fable 5.2 agents formalized Fermat’s Last Theorem in 30 hours, translating the proof into a language a computer can check step by step. Anthropic’s earlier attempt took 11 days. Opus 5.5 completed only 26% in the same setup.
Hardware Engineers and Robotics Teams
Main features: computer aided design, circuit design, robot control.
From a one paragraph prompt, Fable 5.2 designed a voice assistant hub, a USB speakerphone and a handheld virtual pet, picking parts, laying out circuit boards, modeling the cases and writing the software. All three worked without any electrical fixes. It also controlled robots to solve a puzzle cube and unscrew a bottle cap.
Lawyers and Business Analysts
Main features: document review, knowledge work.
Legal AI company Harvey said Fable 5.2 gave clearer direction in an employment compliance review, naming which employees needed attention and how to fix each issue. Box found it flagged a loan application where salary deposits didn’t match the bank balance.
Safety and Honesty Improvements
Anthropic tested the model across roughly 1,900 scenarios. It scored better than earlier models on most measures of misleading users, including making things up, falsely claiming a task was finished and hiding sloppy work. One Cognition engineer said Fable 5.2 admitted its earlier estimate was wrong and refused to guess until it had measured the change.
Claude Fable 5.2 Pricing: Free vs Paid Plans vs API
Let’s clear up the biggest question first: Claude Fable 5.2 is not free. Anthropic’s help center says plainly that Fable models aren’t available on the Free plan. Free users get Claude’s Sonnet and Haiku models instead.
There are two ways to pay for Fable 5.2, and they work very differently.
Option 1: A Claude Subscription (for Everyday Users)
| Plan | Price | What you get |
|---|---|---|
| Free | $0 | Sonnet and Haiku models only, no Fable 5.2. Good for casual questions and trying Claude out |
| Pro | $20 a month ($17 billed yearly) | Fable 5.2 included free until November 16, 2026, then paid with usage credits. Good for individuals who want the top model occasionally |
| Max | $100 a month | Fable 5.2 for up to half your weekly limit, plus a $100 monthly API credit. Good for heavy users, developers and researchers |
| Ultra | $200 a month | Fable 5.2 for up to half your weekly limit, plus a $200 monthly API credit. Good for power users running long projects |
| Team | $25 per standard seat or $125 per premium seat ($20 or $100 billed yearly) | Fable 5.2 included for every seat. Good for companies and work teams |
| Enterprise | $20 per seat billed yearly, plus usage at API rates | Fable 5.2 included. Good for large organizations |
One catch worth knowing: Anthropic says Fable models use up your usage limits faster than other models. That’s because Fable does much more thinking per answer, so each message costs more behind the scenes.
Option 2: The API (for Developers and Businesses)
Developers who build apps or tools pay per token, which is roughly a small chunk of a word.
| Option | Input (per million tokens) | Output (per million tokens) | Why choose it |
|---|---|---|---|
| Fable 5.1 (old price) | $10 | $50 | Previous version |
| Fable 5.2 standard | $8 | $40 | Smarter, faster and 20% cheaper |
| Fable 5.2 fast mode | $16 | $80 | Up to 2.5 times faster answers |
| Cache reads | $0.20 | n/a | Reusing the same long context is far cheaper |
Why the Prices Are Different
Output costs more than input. Reading your question is easy for the model. Writing a careful answer takes far more computing power, so output tokens cost five times as much.
Fast mode costs double. You’re paying Anthropic to put more computing power on your request so answers stream out faster. It’s worth it when a developer or trader needs results right away, and a waste for work that can wait.
Cache reads are cheap. If your app sends the same long document or instructions again and again, the model can reuse what it already processed instead of reading it fresh. That saves a lot of money for businesses running thousands of requests.
Effort levels change your bill too. Higher effort means more thinking tokens and a bigger cost per task. The smart move is to match effort to the job. For example, Fable 5.2 at Low effort matched Opus 5.5’s best score on Humanity’s Last Exam for less than one tenth of the cost.
What About Mythos 5.2?
Mythos 5.2 isn’t sold to the general public, so there’s no consumer plan for it. Approved organizations get access through Anthropic’s Cyber and Life Sciences verification programs, and Claude Enterprise customers can use it indirectly through Claude Security.
Which Option Is Right for You?
- Just curious? Stick with the Free plan. Sonnet and Haiku handle most everyday tasks well.
- Want to try the top model? Pro gives you Fable 5.2 at no extra cost until November 16, a great window to test it.
- Using it daily for serious work? Max or Ultra gives you much more room before hitting limits.
- Building an app? Use the API and start with standard pricing, then add fast mode only where speed truly matters.
When Should You Use Fable 5.2?
Anthropic itself recommends starting most everyday coding and knowledge tasks with Claude Opus 5.5, its main daily model. Move up to Fable or Mythos for the most ambitious, open ended technical work, or down to Sonnet 5.5 or Haiku 5.5 for lighter jobs.
The Bottom Line
Claude Fable 5.2 and Mythos 5.2 are one powerful brain wearing two different safety outfits. Fable is the version almost anyone can use for coding, finance, science and research. Mythos is the unlocked version reserved for vetted security and biomedical teams.
What impresses me most isn’t any single benchmark. It’s that the model can now lead teams of other AI agents through days long projects and finish them. Whether you write code, analyze markets or run experiments, that shift from AI assistant to AI project lead is the real story here.

Leave a Reply